Refineries
What is a Refinery?
A refinery is a command that creates a record while simultaneously creating a relationship and relationship type associated with that same record. A refinery can also match on an existing record in a database, and create a relationship between that record and the source data.
A refinery takes a particular data format in given source data, and transforms it through a specific behavior as it is imported into CollectiveAccess. In other words, refineries tell CollectiveAccess how to import certain data, such as names, dates, and relationships, through a specific text command. This then determines how the data will be displayed once it is imported.
A refinery, at a simplistic level, is what it sounds like - it refines an individual data import mapping and allows for greater complexity in data representation.
If a data import requires related records, then refineries must be used. For more on how to implement these in an import mapping, and why, see Relationships and Creating an Import Mapping: Overview page.
Types of Refineries
There are a few types of refineries commonly used in CollectiveAccess:
- Splitters: A Splitter creates records, matches records with existing data, or parses apart specific data elements, literally "splitting" apart values, such as first and last names. Splitters can be applied to a variety of primary tables in CollectiveAccess. For more on Splitters, see Splitters in the Import Mapping tutorial.
- Joiners: A Joiner is used primarily for data that includes names and dates. Joiners are used when two or more parts of a name located in different areas of the data source need to be conjoined into a single record. A dateJoiner makes a single range out of two or more dates in the data source.
- Builders: A Builder creates an upper hierarchy above the to-be-imported data. For more, see Builders.
Splitters
entitySplitter
Creates an Entity Record or finds an exact match on Entity Name, and creates a relationship as defined in the import mapping. Breaks up parts of names, sets Entity type, and other parameters.
entitySplittler parameters:
- delimiter
- relationshipType
- entityType
- attributes
- relationshipTypeDefault
- entityTypeDefault
- interstitial
- relatedEntities
- nonPreferredLabels
- parents
- skipIfValue
- relationships
- matchOn
- displaynameFormat
- doNotParse
- dontCreate
- ignoreParent
collectionSplitter
Creates a Collection Record or finds an exact match on name, and creates a flat relationshp to the imported record, with the parent parameter building an upper hierarchy above the related collection.
Builds a hierarchy when the import table is set to ca_collections
collectionSplittler parameters:
- delimiter
- relationshipType
- collectionType
- attributes
- relationshipTypeDefault
- collectionTypeDefault
- parents
- nonPreferredLabels
- interstitial
- skipIfValue
- relationships
- matchOn
- ignoreParent
- dontCreate
placeSplitter
Creates a Place Record or finds an exact match on name, and creates a relationship as defined in the import mapping
placeSplitter parameters:
delimiter; relationshipType; placeType; attributes; relationshipTypeDefault; placeTypeDefault; placeHierarchy; nonPreferredLabels; interstitial; parents; relationships; matchOn; ignoreParent; dontCreate
movementSplitter
Creates a Movement Record or finds an exact match on name, and creates a relationship
movementSplitter parameters:
delimiter; relationshipType; movementType; attributes; parents; relationshipTypeDefault; movementTypeDefault; nonPreferredLabels; insterstitial; relationships; matchOn; ignoreParent; dontCreate
objectLotSplitter
Creates an Object Lot Record or finds an exact match on name, and creates a relationship
objectLotSplitter parameters:
delimiter; relationshipType; objectLotStatus; objectLotStatusDefault; objectLotType; attributes; relationshipTypeDefault; objectLotTypeDefault; nonPreferredLabels; interstitial; relationships; matchOn; ignoreParent; dontCreate
objectSplitter
Creates an Object Record or finds an exact match on name, and creates a relationship
objectSplitter parameters:
delimiter; relationshipType; objectType; attributes; parents; relationshipTypeDefault; objectTypeDefault; nonPreferredLabels; interstitial; relationships; matchOn; ignoreParent; dontCreate
objectRepresentationSplitter
Locates media by finding an exact match on filename, and generates an Object Representation for the object being imported
Splitter should be mapped to the name of the media to be imported
objectRepresentationSplitter parameters:
objectRepresentationType; attributes; mediaPrefix; matchOn; dontCreate
occurrenceSplitter
Creates an Occurrence Record or finds an exact match on name, and creates a relationship
occurrenceSplitter parameters:
delimiter; relationshipType; occurrenceType; attributes; parents; relationshipTypeDefault; occurrenceTypeDefault; nonPreferredLabels; interstitial; relationships; matchOn; ignoreParent; dontCreate
listItemSplitter
Creates a List Item or finds an exact match on name, and creates a relationship
listItemSplitter parameters:
delimiter; relationshipType; listItemType; attributes; parents; list; relationshipTypeDefault; listItemTypeDefault; interstitial; relationships; matchOn; ignoreParent; dontCreate
storageLocationSplitter
Creates a Storage Location Record or finds an exact match on name, and creates a relationship
storageLocationSplitter parameters:
hierarchicalStorageLocationTypes; delimiter; hierarchicalDelimiter; parents; nonPreferredLabels; interstitial; relationshipType; storageLocationType; attributes; relationshipTypeDefault; storageLocationTypeDefault; relationships; matchOn; ignoreParent; dontCreate
loanSplitter
Creates a Loan Record or finds an exact match on name, and creates a relationship
The loanSplitter creates new records, and as result, full container paths must be specified in the attributes parameter (for example, ca_table.container_code.subElement_code)
loanSplitter parameters
loanType; relationshipType; delimiter; attributes; relationshipTypeDefault; loanTypeDefault; interstitial; parents; relationships; matchOn; ignoreParent; dontCreate
measurementsSplitter
Formats data values that are mapped to an element of the datatype Length or Weight. Will parse dimension expressions in the form dimension1/delimiter/dimension2, and so on
Parsing includes applying default dimensions when none are specified, stripping extraneous trailing text and normalizing unit specifications. The measurementsSplitter does not create new records; it only maps data. As a result, full container paths must be specified in the attributes/elements parameter (for example, use subElement_code or measurementsWidth)
measurementsSplitter parameters:
delimiter; units; elements; attributes
tourStopSplitter
Creates a Tour Stop Record or finds an exact match on name, and creates a relationship
tourStopSplitter parameter:
delimiter; relationshipType; tourStopType; attributes; tour; relationshipTypeDefault; tourStopTypeDefault; nonPreferredLabels; interstitial; relationships; ignoreParent; dontCreate
tourMaker
Creates a tour parent in a tour stop mapping
tourMaker parameters:
tourType; attributes; tourTypeDefault
Joiners
entityJoiner
Merges data from two or more source data columns to make a single entity record (when first and last Entity names are in two different columns, for example).
entityJoiner parameters:
entityType; entityTypeDefault; forename; surname; other_forenames; middlename; displayname; prefix; suffix; attributes; nonPreferred_labels; relationshipType; relationshipTypeDefault; skipifValue; relatedEntities; interstitial
dateJoiner
Merges data from two or more source data columns to make a single data field in CollectiveAccess
Any text wapped with the date() function will parse as a numeric value that can be then compared as is with any other numeric quanitity. For example: "date(^start) > date(^end)" will evaluate true if the "start" date is after the end date.
dateJoiner parameters:
mode; month; day; year; startDay; startMonth; startYear; endDay; endMonth; endYear; expression; start; end; skipStartIfExpression; skipStartIfExpressionReplacementValue; skipEndIfExpression; skipEndIfExpressionReplacementValue
dateAccuracyJoiner
Merges a date input field with an accuracy input field, where the source data specifies granularity of a date in a separate column from the date value. For example, a date of 2014-04-01 with an accuracy of month would result in the date 2014-04 being stored in CollectiveAccess
Map the date value field into the CA attribute, then use the refinery and refinery settings to specify other parameters.
dateAccuracyJoiner parameters:
accuracyField; dateFormat; accuracyValueDay; accuracyValueMonth; accuracyValueYear; dateParseFailureReturnMode; unknownAccuracyValueReturnMode
Builders
entityHierarchyBuilder
Creates an upper hierarchy of occurrences only when the table of the import is set to ca_entities
Map the CA table.element (Column 3 in an import mapping) to ca_entities.parent_id instead of ca_entities
entityHierarchyBuilder parameters:
parents; doNotParse
collectionHierarchyBuilder
Creates an upper hierarchy of collections only when the import table is set to ca_collections
Map the CA table.element (Column 3 in an import mapping) to ca_collectionss.parent_id instead of ca_collections
collectionHierarchyBuilder parameters:
parents; relationships
collectionIndentedHierarchyBuilder
collectionIndentedHierarchyBuilder parameters:
levels; levelTypes; mode
placeHierarchyBuilder
Creates an upper hierarchy of places only when the import table is set to ca_places
Map the CA table.element (Column 3 in an import mapping) to ca_places.parent_id instead of ca_places
placeHierarchyBuilder parameters:
parents; relationships
objectHierarchyBuilder
Imports a hierarchy of List Items when the import table is set to ca_objects
Map the CA table.element (Column 3 in an import mapping) to ca_objects.parent_id instead of ca_objects
objectHierarchyBuilder parameters:
parents; matchOn; dontMatchOnLabel; relationships
occurrenceHierarchyBuilder
Creates an upper hierarchy fo occurrences only when the import table is set to ca_occurrences
Map the CA table.element (Column 3 in an import mapping) to ca_occurrences.parent_id instead of ca_occurrences for occurrence_Splitter
occurrenceHierarchyBuilder parameters:
parents; relationships
listItemHierarchyBuilder
Imports a hierarchy of List Items when the import table is set to ca_list_items
Map the CA table.element (Column 3 in an import mapping) to ca_list_items.parent_id instead of ca_list_items for listItemSplitter
listItemHierarchyBuilder parameters:
parents; list; relationships
listItemIndentedHierarchyBuilder
Builds a hierarchical list from data sources where indents are used (in Excel) to indicate a hierarchical structure
The list can be imported without relationships to any extant or newly created records; the list can be imported in context of and as metadata for an import that maps authority records of another type (objects that carry the list items as metadata)
listItemIndentedHierarchyBuilder parameters:
levels; levelTypes; list; mode
storageLocationHierarchyBuilder
Creates an upper hierarchy fo occurrences only when the import table is set to ca_occurrences
Map the CA table.element (Column 3 in an import mapping) to ca_storage_locations.parent_id instead of ca_storage_locations for storageLocationSplitter
storageLocationHierarchyBuilder parameters:
parents; relationships
Refinery Parameters
Refineries can't function properly without refinery parameters. Refinery parameters simply define the conditions for the refinery. An example is below:
| refinery | refinery parameter |
|---|---|
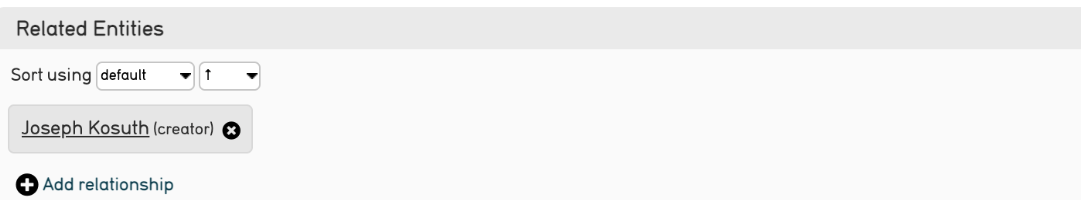
| entitySplitter | {"relationshipType": "creator", "entityType": "ind"} |
To the left (example Column 6) is the actual refinery itself, made up of CollectiveAccess-specific text that is one continuous string. On the right is the refinery parameter, written in JSON. What is this telling the source data to do?
There are no spaces used in writing Refineries.
The refinery, entitySplitter, is telling CollectiveAccess that within the source data there is a name that should be parsed, or, literally "split," or separated (first, last). Therefore, during the import CollectiveAccess will be able to identify what source data falls under this command, and execute it.
The refinery parameter is further defining the refinery by stating the type of relationship that the source data should have and the type of entity that is being imported. In this example, the names apply to a single individual (the entityType) and the relationship to the objects is the relationshipType of "creator."
Once imported into CollectiveAccess, this refinery and its parameter that exists in the import mapping will look like:
Note that Refineries are optional. If source data does not require more complex elements, they are not needed in a mapping. However, Refineries are extremely useful in pre-defining these more complex elements which determine how data is inter-connected, and automatically importing data in the most straightforward, and logical, format.
For a comprehensive list of refinery parameters for each refinery, see the tables below.
Refinery Parameter Definitions
attributes
Sets or maps metadata for the entity record by referencing the metadataElement code and the location in the data source where the data values can be found
{
  "attributes": {
    "idno": "OBJ.2017.1",
    "address": {
      "address1": "^24",
      "address2": "^25",
      "city": "^26",
      "stateprovince": "^27",
      "postalcode": "^28",
      "country": "^29"
    }
  }
}
{
  "attributes": {
    "media": "^1",
    "internal_notes": "^2",
    "idno": "^1"
  }
}
measurementSplitter usage
When using attribute in a measurementSplitter refinery, this maps to other non-measurement elements that may be in the same container. Values here are set for all measurements being split.
auto-generated idno
To map source data to idnos in a *Splitter, see the ‘attributes’ parameter above. An exception exists for when idnos are set to be auto-generated. To create auto-generated idnos within an *Splitter, use the following syntax.
{ "attributes":{"idno": "%"}}
Can be used with: entitySplitter, entityJoiner, collectionSplitter, placeSplitter, movementSplitter, objectLotSplitter, objectSplitter, objectRepresentationSplitter, occurrenceSplitter, listItemSplitter, storageLocationSplitter, loanSplitter, measurementSplitter, tourStopSplitter, tourMarker.
collectionType
Accepts a constant list item idno from the list collection_types or a reference to the location in the data source where the type can be found
{"collectionType": "box"}
Can be used with: collectionSplitter
collectionTypeDefault
Sets the default collection type that will be used if none are defined or if the data source values do not match any values in the CollectiveAccess list collection_types
{"collectionTypeDefault":"series"}
Can be used with: collectionSplitter
dateAccuracyJoiner specific parameters
These parameters are only used on the dateAccuracyJoiner refinery
accuracyField (required)
The field in which the date accuracy is stored (case-insensitive values are defined by accuracyValueDay, accuracyValueMonth and accuracyValueYear settings).
When referencing a source data column, you don't use prefix this with the usual '^' caret.
{ "accuracyField": "14" }
dateFormat
The format in which the input dates are expected. Defaults to ‘Y-m-d’ (2014-04-01). Values come from phpDateTime::createFromFormat()
// Would parse 15-Feb-2009
{ "dateFormat": "j-M-Y"}
accuracyValueDay
The case-insensitive value in the accuracy field that indicates that the date is accurate to the day. Default value is ‘day’.
{ "accuracyValueDay": "d" }
accuracyValueMonth
The case-insensitive value in the accuracy field that indicates that the date is accurate to the month. Default value is ‘month’.
{ "accuracyValueMonth": "m" }
accuracyValueYear
The case-insensitive value in the accuracy field that indicates that the date is accurate to the year. Default value is ‘year’.
{ "accuracyValueYear": "y" }
dateParseFailureReturnMode
Defines what should be returned if the input date cannot be parsed, available values are "null" (the default) and "original"
{ "dateParseFailureReturnMode": "original" }
unknownAccuracyValueReturnMode
Defines what should be returned if the value of the accuracy column is unknown, available values are "null", "original" and "normalised" (the default)
{ "unknownAccuracyValueReturnMode": "null" }
dateJoiner specific parameters
These parameters are only used on the dateJoiner refinery
mode
Determines how dateJoiner joins date values together. Two-column range (aka "range") is the default if mode is not specified. Options are: multiColumnDate, multiColumnRange, range.
{"mode": "multiColumnDate"}
for mode parameter in collectionHierarchyBuilder and listItemHierarchyBuilder see other mode definition
month
Maps the month value for the date from the data source. (For Multi-column date)
{"month": "^4"}
day
Maps the day value for the date from the data source. (For Multi-column date)
{"day": "^5"}
year
Maps the year value for the date from the data source. (For Multi-column date)
{"year": "^6"}
startDay
Maps the day value for the start date from the data source. (For Multi-column range)
{"startDay": "^4"}
startMonth
Maps the month value for the start date from the data source. (For Multi-column range)
{"startMonth": "^5"}
startYear
Maps the year value for the start date from the data source. (For Multi-column range)
{"startYear": "^6"}
endDay
Maps the day value for the end date from the data source. (For Multi-column range)
{"endDay": "^7"}
endMonth
Maps the month value for the end date from the data source. (For Multi-column range)
{"endMonth": "^8"}
endYear
Maps the year value for the end date from the data source. (For Multi-column range)
{"endYear": "^9"}
expression
Date expression (For Two-column range)
{"expression" : "^dateExpression"}
start
Maps the date from the data source that is the beginning of the conjoined date range. (For Two-column range)
{"start" : "^dateBegin"}
end
Maps the date from the data source that is the end of the conjoined date range. (For Two-column range)
{"end": "^dateEnd"}
skipStartIfExpression
Expression that if evaluating to true "start" date is omitted from joined range. Note "date" function – see above.
{"skipEndIfExpression": "date(^end) < 1800"}
skipStartIfExpressionReplacementValue
Optional replacement value for start date when it is skipped by expression. Allows you to force start date to something if skip expression is true.
{"skipStartIfExpressionReplacementValue": "unknown"}
skipEndIfExpression
Expression that if evaluating to true "end" date is omitted from joined range. Note "date" function – see above.
{"skipEndIfExpression": "date(^end) > 2020"}
skipEndIfExpressionReplacementValue
Optional replacement value for end date when it is skipped by expression. This exists to allow you to force the end date to something specific like "present" for living artist’s life dates.
{"skipEndIfExpressionReplacementValue": "present"}
delimiter
Sets the value of the delimiter to break on, separating data source values
{"delimiter": ";"}
{"delimiter": "x"}
Can be used with: entitySplitter, collectionSplitter, placeSplitter, movementSplitter, objectLotSplitter, objectSplitter, objectRepresentationSplitter, occurrenceSplitter, listItemSplitter, storageLocationSplitter, loanSplitter, measurementSplitter, tourStopSplitter.
displayNameFormat
From version 1.5. Allows you to format the output of the displayName. Options are: "surnameCommaForename" (forces display name to be surname, forename); "forenameCommaSurname" (forces display name to be forename, surname); "forenameSurname" (forces display name to be forename surname); "original" (is the same as leaving it blank; you just get display name set to the imported text). This option also supports an arbitrary format by using the sub-element codes in a template, i.e. "^surname, ^forename ^middlename". Doesn’t support full format templating with <unit> and <ifdef> tags, though.
{ "displayNameFormat": "surnameCommaForename" }
Can be used with: entitySplitter.
doNotParse
From version 1.7. This setting will force the import to migrate an organization’s name as is when using the "entity_class" = ORG setting. Otherwise parts of the name get lost in the parse.
{ "doNotParse" "1" }
Can be used with: entitySplitter.
dontCreate
From version 1.5. If set to true (or any non-zero value) the splitter will only do matching and will not create new records when matches are not found.
{ "dontCreate" "1" }
Can be used with: entitySplitter, collectionSplitter, placeSplitter, movementSplitter, objectLotSplitter, objectSplitter, objectRepresentationSplitter, occurrenceSplitter, listItemSplitter, storageLocationSplitter, loanSplitter, tourStopSplitter.
dontMatchOnLabel
Setting dontMatchOnLabel to 1 will cause the the objectHierarchyBuilder to match on object idno, rather than preferred labels. Set this when unique objects may have duplicate titles with other unique objects.
{ "dontMatchOnLabel": "1" }
Can be used with: objectHierarchyBuilder.
elements
Maps the components of the dimensions to specific metadata elements
{
  "elements": [
  {
    "quantityElement": "measurementWidth",
    "typeElement": "measurementsType",
    "type": "width"
  },
  {
    "quantityElement": "measurementHeight",
    "typeElement": "measurementsType2",
    "type": "height"
  }
  ]
}
Note: the typeElement and type sub-components are optional and should only be used in measurement containers that include a type drop-down.
Can be used with: measurementsSplitter
entityType
Accepts a constant list item idno from the list entity_types or a reference to the location in the data source where the type can be found
{ "entityType": "individual"}
Can be used with entitySplitter, entityJoiner
entityTypeDefault
Sets the default entity type that will be used if none are defined or if the data source values do not match any values in the CollectiveAccess list entity_types
{ "entityTypeDefault": "individual"}
Can be used with entitySplitter, entityJoiner
entityJoiner specific parameters
These parameters are for use in entityJoiner refinery.
forename
Accepts a constant value for the forename or a reference to the location in the data source where the forename can be found.
{ "forename": "^3"}
surname
Accepts a constant value for the surname or a reference to the location in the data source where the surname can be found.
{ "surname": "^2"}
other_forenames
Accepts a constant value for the entity’s other forenames or a reference to the location in the data source where the other forenames can be found.
{ "other_forenames": "^4"}
middlename
Accepts a constant value for the middlename or a reference to the location in the data source where the middlename can be found.
{ "middlename": "^5"}
displayname
Accepts a constant value for the displayname or a reference to the location in the data source where the displayname can be found.
{ "displayname": "^1"}
prefix
Accepts a constant value for the prefix or a reference to the location in the data source where the prefix can be found.
{ "prefix": "^6"}
suffix
Accepts a constant value for the suffix or a reference to the location in the data source where the suffix can be found.
{ "suffix": "^7"}
nonpreferred_labels
List of non-preferred label values or references to locations in the data source where nonpreferred label values can be found. Use the split value for a label to indicate a value that should be split into entity label components before import.
{
  "nonpreferred_labels": [{
    "forename": "^5",
    "surname": "^6"
  }]
}
OR
{
  "nonpreferred_labels": [{"split": "^4"}]
}
hierarchicalDelimiter
Can be used with storageLocationSplitter
hierarchicalStorageLocationTypes
Can be used with storageLocationSplitter
ignoreParent
From version 1.5. For use with entity hierarchies. When set to true this parameter allows global match across the entire hierarchy, regardless of parent_id. Use this parameter with datasets that include values to be merged into existing hierarchies but that do not include parent information. Paired with matchOn it’s possible to merge the values using only name or idno, without any need for hierarchy info. Not ideal for situations where multiple matches can not be disambiguated with the information available.
{ "ignoreParent" "1" }
Can be used with entitySplitter, collectionSplitter, placeSplitter, movementSplitter, objectLotSplitter, objectSplitter, occurrenceSplitter, listItemSplitter, storageLocationSplitter, loanSplitter, tourStopSplitter
interstitial
Sets or maps metadata for the interstitial movement Relationship record by referencing the metadataElement code and the location in the data source where the data values can be found.
{ "interstitial":
  {
    "relationshipDate": "^4"
  }
}
Can be used with entitySplitter, entityJoiner, collectionSplitter, placeSplitter, objectLotSplitter, objectSplitter, occurrenceSplitter, listItemSplitter, storageLocationSplitter, loanSplitter, tourStopSplitter
levels
List of sources for hierarchy levels
{
  "levels":["^1", "^2", "^3"]
}
Can be used with collectionIndentedHierarchyBuilder, listItemIndentedHierarchyBuilder
levelTypes
List of types for hierarchy levels
{
  "levelTypes":["collection", "series", "item"]
}
Can be used with collectionIndentedHierarchyBuilder, listItemIndentedHierarchyBuilder
list
Code of list to import items into
{
  "list":"object_classification"
}
Can be used with listItemIndentedHierarchyBuilder, listItemHierarchyBuilder
listItemType
Accepts a constant list item idno from the list or a reference to the location in the data source where the type can be found.
{
  "listItemType": "concept"
}
Can be used with listItemSplitter
listItemTypeDefault
Sets the default list item type that will be used if none are defined or if the data source values do not match any values in the CollectiveAccess list list_item_types
{
  "listItemTypeDefault":"concept"
}
Can be used with listItemSplitter
loanType
Accepts a constant list item from the list loan_types
{
  "loanType":"out"
}
Can be used with loanSplitter
loanTypeDefault
Sets the default loan type that will be used if none are defined or if the data source values do not match any values in the CollectiveAccess list loan_types.
{
  "loanTypeDefault":"in"
}
Can be used with loanSplitter
matchOn
From version 1.5. Defines exactly how the splitter will establish matches with pre-existing records. For example, you might be importing a data set in which entities are only listed by last name, but you want to make sure those entities merge with pre-existing records that include the full name. In that case, you could set "matchOn" to "surname." Or perhaps the data set includes multiple individuals with identical names. Here you might want to match on "idno" instead. You can also list multiple fields in the matchOn parameter, and it will try multiple matches in the order specified.
{ "matchOn": ["labels","idno"]}
{ "matchOn": ["idno","labels"]}
You can also limit matching by doing one or the other.
{ "matchOn": ["idno"]}
{ "matchOn": ["surname"]}
Or match on a custom metadata element in the record using the syntax ^ca_entities.metadataElement_code. Swap ca_entities for the table you are mapping to
{ "matchOn": ["^ca_entities.your_custom_code"]}
Can be used with entitySplitter, collectionSplitter, placeSplitter, movementSplitter, objectLotSplitter, objectSplitter, objectRepresentationSplitter, objectHierarchyBuilder, occurrenceSplitter, listItemSplitter, storageLocationSplitter, loanSplitter
mediaPrefix
Can be used with
mode
Can be used with
movementType
Can be used with
movementTypeDefault
Can be used with
nonPreferredLabels
Maps source data cells to <table>.nonpreferred_labels of the record being generated or matched by the *Splitter. Created as a list, can define more than one nonPreferredLabel.
{
  "nonPreferredLabels":
  [{
    "forename": "^5",
    "surname":"^6"
  }]
}
{
  "nonPreferredLabels": [
    {
      "forename": "^5",
      "surname":"^6"
    },
    {
      "forname": "^7",
      "surname": "^8"
    }
  ]
}
Can be used with entitySplitter, collectionSplitter, placeSplitter, movementSplitter, objectLotSplitter, objectSplitter, occurrenceSplitter, storageLocationSplitter, tourStopSplitter
objectType
Can be used with
objectTypeDefault
Can be used with
objectLotStatus
Can be used with
objectLotStatusDefault
Can be used with
objectLotType
Can be used with
objectLotTypeDefault
Can be used with
objectRepresentationType
Can be used with
occurrenceType
Can be used with
occurrenceTypeDefault
Can be used with
parents
Maps or builds the hierarchical records above the record being generated or matched by the *Splitter. The parent parameter has several sub-parameters including:
- idno: maps the level-specific idno
- name: maps the level-specific preferred_label
- type: maps the level-specific record type (must match the item idno exactly)
- attributes: maps the (optional) level-specific metadata. Includes the metadataElement code and the data source.
- rules: maps any (optional) level-specific rules
{
  "parents": [
    {
      "idno": "^5",
      "name": "^6",
      "type": "organization",
      "attributes": {
        "ca_entities.description": "^7"
      }
    }
  ]
}
{
  "parents": [
    {
      "idno": "^/inm:SeriesNo",
      "name": "^/inm:SeriesTitle",
      "type": "series",
      "attributes": { "ca_collections.description": "^7"}
    },
    {
      "idno": "^/inm:CollectionNo",
      "name": "^/inm:CollectionTitle",
      "type": "collection",
      "rules": [{
        "trigger": "^/inm:Status = ‘in progress’",
        "actions": [{
          "action": "SET",
          "target": "ca_collections.status",
          "value": "edit"
        }]
      }]
    }
  ]
}
Can be used with
placeType
Can be used with
placeTypeDefault
Can be used with
placeHierarchy
Can be used with
preferredLabel
Can be used with:
relatedEntities
This allows you to create and/or relate additional entities to the entity being mapped. For example, if you are running an Object mapping and using an entitySplitter to generate related Individuals, but you also want to create entity records for each individual’s affiliation, use this setting. "Name" is the name of the entity, which will be automatically split into pieces and imported. If you want to explicitly map pieces of a name (surname, forename) you can omit "name" and use "forename", "middlename", "surname", etc. "type", "attributes," and "relationshipType" operate just as they would in a regular splitter.From version 1.5 this is now deprecated in favor of the ‘relationships’ setting.
{"relatedEntities":
  [{
    "type":"ind",
    "name": "^3",
    "attributes":{},
    "relationshipType":"related"
  }]
}
Can be used with
relationships
From version 1.5. A list of relationships using the relevant splitter refineries. The settings for this item reflect the settings used for the relevant splitter refinery. The only additional setting here is relatedTable which is a required value.
{
  "relationships"[
    {
      "relatedTable": "ca_objects",
      "type" : "moving_image",
      "relationshipType": "creator",
      "preferredLabel": "^7",
      "attributes" : {
        "technique" : "^10"
      }
    },
    {
      "relatedTable": "ca_entities",
      "type" : "individual",
      "relationshipType": "parent",
      "preferredLabels" : [{"forename": "^5", "surname":"^6"}],
      "attributes" : {
        "gender" : "^33",
        "phone" : "^34"
      }
    }
  ]
}
Can be used with
relationshipType
Accepts a constant type code for the relationship type (read more about relationships) or a reference to the location in the data source where the type can be found
{ "relationshipType": "^10" }
{ "relationshipType": "author" }
{ "relationshipType": "part_of" }
if the relationship type matches that set as the hierarchy control, the object will be pulled in as a "child" element in the collection hierarchy
Can be used with
relationshipTypeDefault
Sets the default relationship type that will be used if none are defined or if the data source values don’t match any values in the CollectiveAccess system
{"relationshipTypeDefault":"creator"}
Can be used with
skipIfValue
Skip if imported value is in the specified list of values.
{ "skipIfValue": "unknown"}
Can be used with
storageLocationType
Can be used with
storageLocationTypeDefault
Can be used with
tour
Can be used with
tourType
Can be used with
tourTypeDefault
Can be used with
tourStopType
Can be used with
tourStopTypeDefault
Can be used with
units
Can be used with